It’s becoming painfully obvious that there is no way to ethically use frontier models powered by these monstrosities. It is currently 100 F in Tuckahoe, the largest city in Henrico County… and they’re asking people to not use electricity so that these heat-and-pollution-generating slop factories can use it instead.
It is currently 100 F in Tuckahoe, the largest city in Henrico County… and they’re asking people to not use electricity so that these heat-and-pollution-generating slop factories can use it instead.
In other words, this shit is killing people? I don’t think many houses in the US are made so that you can survive 38°C outside without A/C ?
Oh, there are definitely ethical ways to use these models. It’s just that those methods are not being enforced by local counties or your governments. Thus, companies are able to do whatever the hell they want, which means it’s going to be unethical by default.
What we need is regulation, enforcement, and a stop letting these companies trample all over everything they want to.
No, there really isn’t. The frontier models are created through massive plagiarism. They’re designed to be addictive to use. They consume massive amounts of resources to feed you slop. They are inherently unethical. We’re burning the planet down to keep them running, and we don’t even have a demonstrable financial ROI to show for it.
Stop using them. If your employer makes you use them, maliciously comply by wasting tokens until the financial pain is too great for them to bear and they stop. If you yourself are addicted, switch to small, local, open-source, open-weight models you can run yourself. You won’t burn the world down running a small model on your own computer.
You have that backwards. The only thing you gain from running local models is privacy. It is not cheaper, it is not more efficient. You are actively hurting the environment MORE by using a local model on your own. LLM efficiency sky rockets the more users there are on a single loaded model.
IMO the only way we get to efficient LLM usage would be by having very efficient non frontier models running only for its local community to use, where you can have assurances on whether its power source is clean or not. That doesn’t help with the plagiarism aspect though
Local model: Spends most of its time turned off. Only active when I want it to be active, and only for a little while. Dedicated solely to generating the small amounts of code I use it for. Does nothing else. Costs $0 per token, and electricity costs are negligible.
Frontier model: Always on, running on millions of GPUs. Would be burning down the planet even if hardly anyone was using it. Incredibly wasteful, being used for trivial tasks and convincing people that their horrible ideas are visionary every day. Misspelling “strawberry” for the masses. Trained specifically to be addictive. Can easily cost a software developer who is addicted to AI thousands of dollars a month, with the recent price increases.
I’d love to see some data to back up the assertion that frontier models are somehow cheaper and more efficient than running a model locally.
You’re probably burning more energy turning it off and on again. It doesn’t really use any noticeable power sitting idle.
Anyway, a direct comparison would be pretty difficult because your model is probably tens of billions of parameters, not over a trillion. Energy consumption per output token will probably be a bit higher for the frontier models but something that people have found is that higher quality models often need fewer tokens to achieve the same goal. Plus how many times do you re-prompt your local model vs Claude Fable or Opus for example to get the desired result?
You’re probably burning more energy turning it off and on again. It doesn’t really use any noticeable power sitting idle.
I am absolutely not burning more energy than a frontier model by doing things like putting my laptop to sleep or shutting down unused services when I want to conserve battery power.
Anyway, a direct comparison would be pretty difficult because your model is probably tens of billions of parameters, not over a trillion.
True.
Energy consumption per output token will probably be a bit higher for the frontier models but something that people have found is that higher quality models often need fewer tokens to achieve the same goal.
That’s actually not true. In fact it’s much the opposite. Frontier models churn through tokens at a much higher rate, because of their higher complexity and higher number of parameters. Research is still new on this, but having a frontier model analyze your code files versus a small, local model for the same task seems to be enormously wasteful. If you must use a frontier model for something, have it do that work after receiving the output from an agent using a small model to read and summarize your code.
Plus how many times do you re-prompt your local model vs Claude Fable or Opus for example to get the desired result?
…Almost never? I’m not a fan of letting AI do much of ANY of my coding, because it will inevitably bloat my codebase with garbage regardless of which model I use. So I severely restrict my model usage to simple, clearly-defined, narrow-scoped tasks that can save me a bit of time, and that’s it. With guardrails and discipline like that, I barely ever have the need to re-prompt.
I am absolutely not burning more energy than a frontier model by doing things like putting my laptop to sleep or shutting down unused services when I want to conserve battery power.
I was under the impression you keep loading the model into VRAM and unloading it when finished using it, I meant it’s less power efficient than just keeping it in VRAM.
That’s actually not true. In fact it’s much the opposite. Frontier models churn through tokens at a much higher rate, because of their higher complexity and higher number of parameters.
Thing is, the input/reading part of it is cheap and wastefully generating extra tokens as output costs you more in energy (or money if using an external service). Put it this way: Claude has historically had 3 models: Haiku (small), Sonnet (medium), Opus (big). Sonnet 5 came out recently and people using Claude Code have reported that it’s so verbose, it’s now more expensive to use for the same task than Opus, which has much bigger costs per Mtok. That would mean it probably also uses more energy than the bigger model.
…Almost never? I’m not a fan of letting AI do much of ANY of my coding, because it will inevitably bloat my codebase with garbage regardless of which model I use. So I severely restrict my model usage to simple, clearly-defined, narrow-scoped tasks that can save me a bit of time, and that’s it. With guardrails and discipline like that, I barely ever have the need to re-prompt.
At that point, why bother with a local model, you could use Deepseek V4 flash and probably spend less than a tenner a month on it. It’s surprisingly capable (I mean sometimes you can barely tell it’s not a frontier model) and costs next to nothing to use.
If you must use a frontier model for something, have it do that work after receiving the output from an agent using a small model to read and summarize your code.
It’s sort of what my workflow does when I use OpenCode. Bigger model (GLM-5.2 or GPT-5.5 depending on which one hasn’t run into its usage limit) reads my prompt, the .md files describing the repo and the overall file structure of the repo, then fires off parallel DeepSeek V4 Flash scouts on usage credits to read and summarize the files as needed. The big model then does the planning and again DeepSeek V4 Flash is the one to execute it via subagents. The subagents running DeepSeek usually come back with 1-2 cents in cost.
I did try a Qwen-3.6 distillation locally and it was pretty capable in terms of output, but it’s more expensive for me than the DeepSeek Flash on API usage costs, since electricity isn’t free here and my GPU is 2 generations old. And it’s slow as hell, since it has to offload a lot to CPU/RAM over GPU/RAM.
The big models I only use as subscriptions that I’m prepared to end at any moment if they reduce the usage I get. Let the AI companies eat the cost, I’ll never pay them API pricing if they want 20 or 30 dollars for a million output tokens.


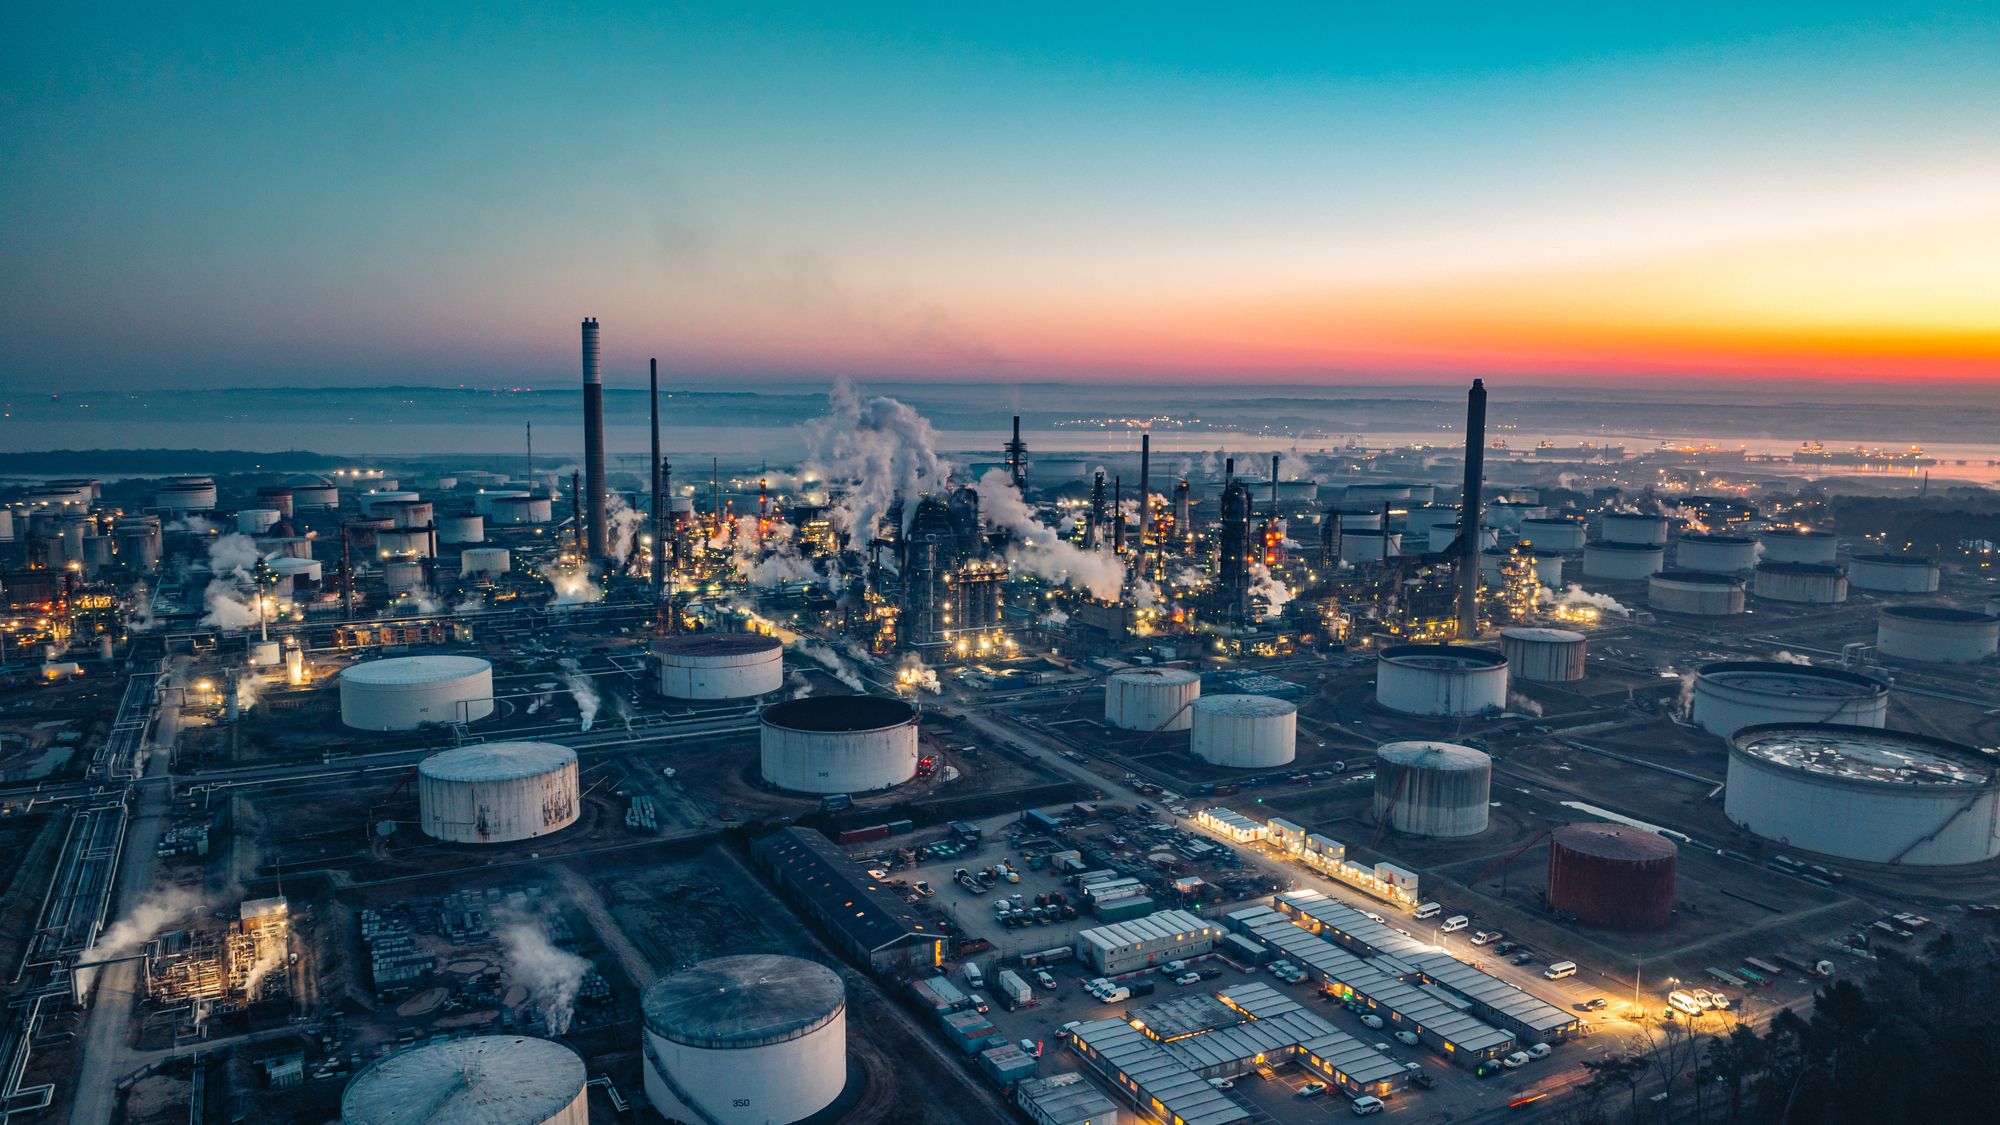
It’s becoming painfully obvious that there is no way to ethically use frontier models powered by these monstrosities. It is currently 100 F in Tuckahoe, the largest city in Henrico County… and they’re asking people to not use electricity so that these heat-and-pollution-generating slop factories can use it instead.
This is insanity.
They are being paid. Why else would they doom their own people? You won’t stop it if you don’t stop them.
The only reasonable response to these requests is fuck you figure out your data center power issues yourself.
Power is for the people.
In other words, this shit is killing people? I don’t think many houses in the US are made so that you can survive 38°C outside without A/C ?
This administration has killed a lot of folks.
Oh, there are definitely ethical ways to use these models. It’s just that those methods are not being enforced by local counties or your governments. Thus, companies are able to do whatever the hell they want, which means it’s going to be unethical by default.
What we need is regulation, enforcement, and a stop letting these companies trample all over everything they want to.
No, there really isn’t. The frontier models are created through massive plagiarism. They’re designed to be addictive to use. They consume massive amounts of resources to feed you slop. They are inherently unethical. We’re burning the planet down to keep them running, and we don’t even have a demonstrable financial ROI to show for it.
Stop using them. If your employer makes you use them, maliciously comply by wasting tokens until the financial pain is too great for them to bear and they stop. If you yourself are addicted, switch to small, local, open-source, open-weight models you can run yourself. You won’t burn the world down running a small model on your own computer.
You have that backwards. The only thing you gain from running local models is privacy. It is not cheaper, it is not more efficient. You are actively hurting the environment MORE by using a local model on your own. LLM efficiency sky rockets the more users there are on a single loaded model.
IMO the only way we get to efficient LLM usage would be by having very efficient non frontier models running only for its local community to use, where you can have assurances on whether its power source is clean or not. That doesn’t help with the plagiarism aspect though
Are you serious?
I’d love to see some data to back up the assertion that frontier models are somehow cheaper and more efficient than running a model locally.
You’re probably burning more energy turning it off and on again. It doesn’t really use any noticeable power sitting idle.
Anyway, a direct comparison would be pretty difficult because your model is probably tens of billions of parameters, not over a trillion. Energy consumption per output token will probably be a bit higher for the frontier models but something that people have found is that higher quality models often need fewer tokens to achieve the same goal. Plus how many times do you re-prompt your local model vs Claude Fable or Opus for example to get the desired result?
I am absolutely not burning more energy than a frontier model by doing things like putting my laptop to sleep or shutting down unused services when I want to conserve battery power.
True.
That’s actually not true. In fact it’s much the opposite. Frontier models churn through tokens at a much higher rate, because of their higher complexity and higher number of parameters. Research is still new on this, but having a frontier model analyze your code files versus a small, local model for the same task seems to be enormously wasteful. If you must use a frontier model for something, have it do that work after receiving the output from an agent using a small model to read and summarize your code.
…Almost never? I’m not a fan of letting AI do much of ANY of my coding, because it will inevitably bloat my codebase with garbage regardless of which model I use. So I severely restrict my model usage to simple, clearly-defined, narrow-scoped tasks that can save me a bit of time, and that’s it. With guardrails and discipline like that, I barely ever have the need to re-prompt.
I was under the impression you keep loading the model into VRAM and unloading it when finished using it, I meant it’s less power efficient than just keeping it in VRAM.
Thing is, the input/reading part of it is cheap and wastefully generating extra tokens as output costs you more in energy (or money if using an external service). Put it this way: Claude has historically had 3 models: Haiku (small), Sonnet (medium), Opus (big). Sonnet 5 came out recently and people using Claude Code have reported that it’s so verbose, it’s now more expensive to use for the same task than Opus, which has much bigger costs per Mtok. That would mean it probably also uses more energy than the bigger model.
At that point, why bother with a local model, you could use Deepseek V4 flash and probably spend less than a tenner a month on it. It’s surprisingly capable (I mean sometimes you can barely tell it’s not a frontier model) and costs next to nothing to use.
It’s sort of what my workflow does when I use OpenCode. Bigger model (GLM-5.2 or GPT-5.5 depending on which one hasn’t run into its usage limit) reads my prompt, the .md files describing the repo and the overall file structure of the repo, then fires off parallel DeepSeek V4 Flash scouts on usage credits to read and summarize the files as needed. The big model then does the planning and again DeepSeek V4 Flash is the one to execute it via subagents. The subagents running DeepSeek usually come back with 1-2 cents in cost.
I did try a Qwen-3.6 distillation locally and it was pretty capable in terms of output, but it’s more expensive for me than the DeepSeek Flash on API usage costs, since electricity isn’t free here and my GPU is 2 generations old. And it’s slow as hell, since it has to offload a lot to CPU/RAM over GPU/RAM.
The big models I only use as subscriptions that I’m prepared to end at any moment if they reduce the usage I get. Let the AI companies eat the cost, I’ll never pay them API pricing if they want 20 or 30 dollars for a million output tokens.